- The Outbox pattern requires CDC tooling like Debezium to reliably bridge transactional databases and message brokers without dual-write failures.
- Because most message brokers guarantee at-least-once delivery, you must implement idempotent consumers using deduplication tables or Redis-based keys.
- Kafka provides per-partition ordering and millions of messages per second, but its JVM overhead makes Redpanda's C++ binary an operationally leaner alternative.
When Should You Avoid Event-Driven Architecture for Microservices?
You don't need a message broker for everything. Standard CRUD applications with no complex workflows (and let's be honest, most apps) are better suited for REST APIs than event-driven architecture due to lower operational overhead. And adding a broker to a system that fits in a single database transaction just creates unnecessary moving parts.
EDA produces eventual consistency. This makes it unsuitable for financial transactions requiring synchronous consistency without careful design, because you can't easily tell a user their funds transferred if the event is still sitting in a queue.
For synchronous operations, blocking calls are correct. On a recent build, I took a synchronous REST API for the payment gateway over the obvious event-driven option, and we eliminated three days of reconciliation scripts. The business needed immediate confirmation.
Event-Driven Architecture for Microservices isn't a silver bullet, and it is a specific tool for high-throughput, loosely coupled domains where you can tolerate asynchronous processing delays.
When developers force a request/response pattern into an event broker, they often build request/reply queues. The producer publishes an event and then blocks, waiting for a correlated response on a reply topic, which introduces a distributed timeout problem. If the consumer is down, the producer hangs until its local timeout fires, returning a generic error to the user anyway.
Consider a user registration flow.
The client sends credentials to the API, which publishes a UserRegistrationRequested event, and the identity service consumes it, hashes the password, and publishes a UserRegistered event. The API listens for this to return the auth token. If the password fails validation rules inside the identity service, the client gets a 500 timeout instead of a 400 Bad Request, and you lose the semantic HTTP status codes.
{
 "eventId": "9876-5432",
 "replyTo": "user-registration-reply-v1",
 "correlationId": "abcd-1234",
 "payload": {
 "email": "user@example.com",
 "password": "weak"
 }
}
The API now has to parse a failure event to figure out why the registration failed. This tight coupling defeats the purpose of asynchronous communication. Use synchronous REST or gRPC for operations requiring immediate validation feedback, and reserve events for fire-and-forget domain notifications.
Step 1: Implement the Transactional Outbox Pattern
The Outbox pattern writes an event into an outbox table inside the same database transaction as the state change to guarantee atomicity. You avoid the dual-write problem where you commit to the database but the broker is down, losing the event.
You can implement this using Debezium for Change Data Capture (CDC) or a custom polling publisher. CDC is superior because it reads the database transaction log directly, adding zero query overhead to your application. A polling publisher is simpler but puts load on your database.
Here is a TypeScript example of wrapping the state change and the outbox insert in a single transaction:
import { Pool } from 'pg';


const pool = new Pool();


async function createOrder(userId: string, amount: number) {
  const client = await pool.connect();
  try {
    await client.query('BEGIN');

    // Insert business state
    const orderRes = await client.query(
      'INSERT INTO orders (user_id, amount, status) VALUES ($1, $2, $3) RETURNING id',
      [userId, amount, 'PENDING']
    );
    const orderId = orderRes.rows[0].id;

    // Insert event into outbox in the same transaction
    await client.query(
      `INSERT INTO outbox (aggregate_type, aggregate_id, event_type, payload)
       VALUES ($1, $2, $3, $4)`,
      ['Order', orderId, 'OrderPlaced', JSON.stringify({ orderId, userId, amount })]
    );

    await client.query('COMMIT');
  } catch (e) {
    await client.query('ROLLBACK');
    throw e;
  } finally {
    client.release();
  }
}
Debezium requires specific connector configurations to route outbox events correctly. You must configure the table.expand.json.payload option to unwrap the JSON payload directly into the Kafka message value.
Consider these requirements when configuring CDC:
- Ensure your database transaction log is enabled and archived.
- Use a separate topic for each event type to isolate consumer failures.
- Monitor the Debezium connector offset to prevent lag during outages.
Step 2: Enforce Schema Evolution and Compatibility
Schema evolution is critical in Event-Driven Architecture for Microservices. Confluent Schema Registry for Kafka and AWS Glue for Kinesis manage schema evolution and enforce compatibility modes, which you need to prevent breaking downstream consumers during deployment. Schema compatibility modes include BACKWARD (new schema reads old), FORWARD (old schema reads new), and FULL (both).
I default to BACKWARD compatibility. It lets you add fields with defaults without breaking old consumers, which is usually exactly what you need for iterative deployments. If you don't enforce schemas, you lose data permanently.
According to Asifthewebguy, AWS SQS maximum message retention is 14 days. If a consumer fails to parse an unregistered schema, the event disappears after that window, and you will never recover it.
Here is an Avro schema configured for BACKWARD compatibility:
{
 "type": "record",
 "name": "OrderPlaced",
 "namespace": "com.orders.events",
 "fields": [
 { "name": "orderId", "type": "string" },
 { "name": "userId", "type": "string" },
 { "name": "amount", "type": "double" },
 { "name": "currency", "type": "string", "default": "USD" }
 ]
}
Adding the currency field with a default keeps this schema BACKWARD compatible. Removing a field or changing a type breaks it, and you must register the schema in the registry before deploying the producer code. Schema registries enforce compatibility at serialization time.
If a producer attempts to serialize a payload using an unregistered schema, the registry rejects it, and the producer throws a serialization exception, blocking the event from reaching the broker. This prevents poison pills from entering your pipeline and crashing consumers.
But simply adding defaults doesn't solve semantic changes. If you change the amount field from representing a gross total to a net total, the schema is technically backward compatible because the field type remains a double, but old consumers will misinterpret the data, causing silent calculation errors in billing systems. To handle semantic shifts, you must introduce a completely new event.
Instead of modifying OrderPlaced, you publish OrderPlacedV2 to a new topic or namespace.
{
 "type": "record",
 "name": "OrderPlacedV2",
 "namespace": "com. orders. events. v2",
 "fields": [
 { "name": "orderId", "type": "string" },
 { "name": "userId", "type": "string" },
 { "name": "grossAmount", "type": "double" },
 { "name": "taxAmount", "type": "double" },
 { "name": "currency", "type": "string", "default": "USD" }
 ]
}
Consumers can subscribe to both topics simultaneously, processing V2 events when available and falling back to V1 for older aggregates. Once all producers migrate to V2, you can deprecate the V1 topic safely. This dual-stream approach allows you to migrate consumers independently without a big-bang deployment, which is the only way I trust major refactors in production.
Step 3: Configure Idempotent Consumers and Dead-Letter Queues
Most message brokers guarantee at-least-once delivery by default, necessitating idempotent consumers. You will receive duplicate messages. If your consumer isn't idempotent, you will double-charge users or double-process orders, creating support tickets and breaking customer trust.
You can set up deduplication using a database table or Redis-based idempotency keys. Before processing an event, check if the event ID exists in your deduplication store, and if it does, skip processing entirely. Events that fail processing after N retries go to a dead-letter queue for manual inspection.
You configure these limits directly on your consumer. For Kafka, you handle retries in application logic or use a retry topic. For AWS SQS, you set maxReceiveCount on the redrive policy.
Here is a YAML snippet for an AWS SQS redrive policy:
RedrivePolicy:
 deadLetterTargetArn: arn:aws:sqs:us-east-1:123456789012:OrderDLQ
 maxReceiveCount: "5"
Every time I have seen this fail, the cause was the same: developers assumed exactly-once delivery from Kafka. The fix was building a Redis-based deduplication key check before processing any business logic. According to Asifthewebguy, RabbitMQ throughput is approximately 100,000 messages per second.
At that volume, a few duplicate deliveries can cause massive duplicate side effects if consumers aren't strictly idempotent.
How Do You Manage Distributed Transactions with the Saga Pattern?
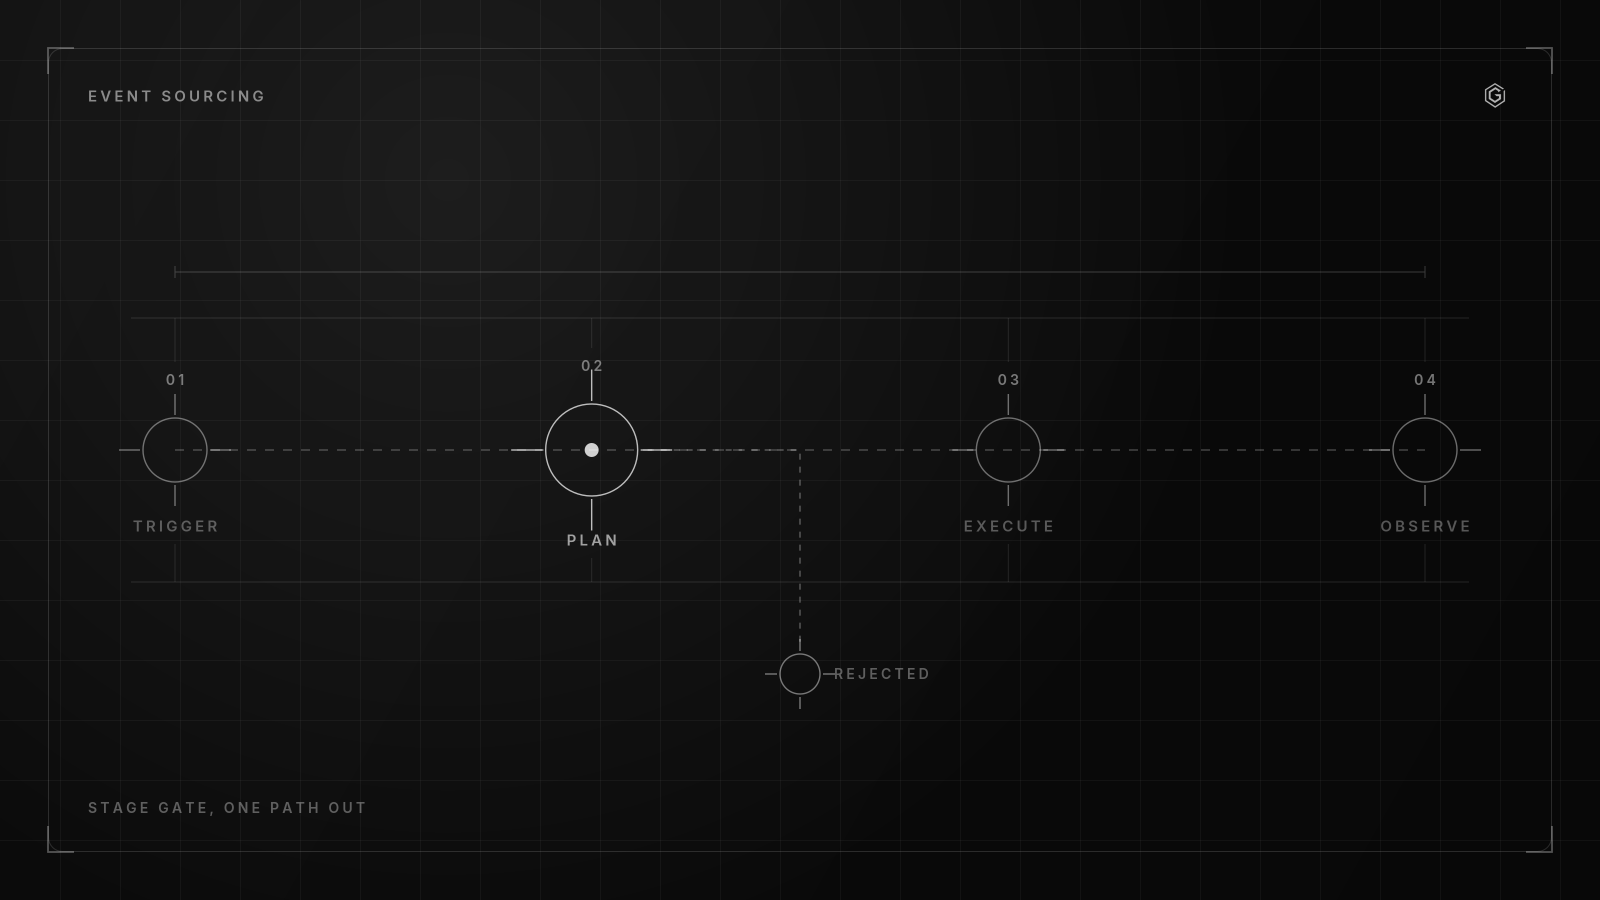
The Saga pattern coordinates multi-step transactions across services by publishing compensating events when downstream failures occur. Event-driven systems are eventually consistent, requiring strategies like idempotent consumers and compensation events to handle temporary inconsistency, because you can't use two-phase commit across microservices. You can set up sagas via choreography or orchestration.
In choreography, each service listens for events and publishes the next step. In orchestration, a central controller tells each service what to do. Choreography works for simple flows.
It fails when you have more than three steps because the logic spreads across the codebase and becomes impossible to trace. Orchestration centralizes the state machine, making failures explicit. If a downstream service fails in a booking workflow, the orchestrator publishes a compensation event, and the upstream services listen for this event and roll back their state.
Compensation isn't a database rollback. It is a business-level undo, meaning if you charged a credit card, compensation issues a refund.
When designing a saga, you must account for non-compensable actions. In a travel booking saga, you might book a flight, book a hotel, and then charge the customer. If the hotel booking fails, you cancel the flight.
But what if the flight booking included a non-refundable ticket purchase? The orchestrator can't simply undo the charge. It must emit a ManualInterventionRequired event, moving the saga to a suspended state.
{
 "sagaId": "saga-8901",
 "currentStep": "BOOK_HOTEL",
 "status": "SUSPENDED",
 "reason": "CompensationFailed",
 "failedAction": "CHARGE_CUSTOMER",
 "compensatedSteps": ["BOOK_FLIGHT"]
}
Orchestration requires a persistent store for the saga state. If the orchestrator crashes mid-saga, it must reload the state from a database and resume or trigger compensations based on a timeout, because you can't hold the state in memory. Choreography has a hidden failure mode: infinite event loops.
If service A publishes an event on failure, and service B consumes it, fails, and publishes a failure event that service A consumes, you can spiral out of control. You must include a saga_id and a step_counter in every event. If a consumer receives an event where the step counter exceeds the maximum allowed retries, it drops the event and alerts an operator.
Building something similar? Let's compare notes.
Response within 24 hours. No commitment required.
Comparing Event Broker Throughput and Ordering Guarantees
Selecting the right broker dictates your system's throughput and ordering guarantees in Event-Driven Architecture for Microservices. Kafka provides per-partition ordering, RabbitMQ provides per-queue ordering, and NATS provides per-subject ordering. Kafka offers event replay by seeking to an offset, whereas RabbitMQ and standard AWS SQS don't support replay, which makes Kafka suitable for event sourcing where you need to rebuild state.
According to Asifthewebguy, Kafka throughput is in the millions of messages per second. And this throughput comes at the cost of operational complexity. You have to manage JVM tuning and cluster state.
Redpanda offers similar throughput using a C++ binary, reducing operational overhead.
Here is a comparison of common brokers:
| Broker | Ordering Guarantee | Replay Support | Max Retention | Throughput |
|---|---|---|---|---|
| Kafka | Per-partition | Yes (offset seek) | Configurable | Millions/sec |
| Redpanda | Per-partition | Yes (offset seek) | Configurable | Millions/sec |
| RabbitMQ | Per-queue | No | Configurable | 100,000/sec |
| AWS SQS | Standard: None, FIFO: Per-group | No | 14 days | Variable |
Choose Kafka or Redpanda when you need replay and high throughput. Choose RabbitMQ when you need complex routing. Choose SQS when you want managed infrastructure and can accept its limits.
The Hidden Operational Tax of Event Sourcing and CQRS
Event sourcing stores state as a sequence of events rather than a single snapshot, appending events to an event store instead of updating database rows. CQRS splits the write path from the read path; commands change state by emitting events, while queries read from purpose-built read models. These patterns are heavily promoted in Event-Driven Architecture for Microservices, and they introduce massive operational complexity for small to medium domains.
You have to manage event versioning, projection rebuilding, and read model lag. A standard CRUD application with an append-only audit log often achieves the same regulatory and debugging goals. You get the current state immediately.
You get the audit trail. You avoid the overhead of rebuilding read models from event streams. But do not adopt event sourcing unless your domain requires temporal queries or absolute state reconstruction.
If you just need to know who changed a field and when, database triggers and history tables are simpler. They are easier to operate.
Observability: Tracing Events and Defining Alert Thresholds
Distributed tracing across an event-driven mesh isn't optional. Without it, debugging failed events becomes impossible, and you must build OpenTelemetry across message brokers to trace events end-to-end. An event in a reactive system should represent a complete snapshot of the state change, and you must propagate the trace context in your event headers.
When a consumer picks up the event, it links the trace to the original producer. To trace events end to end, you inject OpenTelemetry context into message headers. The producer creates a span, serializes the context, and adds it to the Kafka headers or SQS message attributes.
The consumer extracts the context, links it to a new consumer span, and continues the trace.
// Producer
headers := make(map[string]string)
propagator.Inject(ctx, carriers.MapCarrier(headers))
msg := kafka.Message{
 Key: []byte(aggregateId),
 Value: payload,
 Headers: headers,
}


// Consumer ctx := propagator.Extract(context.Background(), carriers.MapCarrier(msg.Headers)) ctx, span := tracer.Start(ctx, "process-event") defer span.End()
If you use AWS SQS, the broker limits message attributes to 10 headers. If you exceed this limit, the SDK throws an error and the event is never sent. You must compress or truncate non-essential trace fields before publishing.
Consumer lag isn't just a raw offset difference. It is the delta between the latest log offset and the committed offset, multiplied by the average message size. A lag of 10,000 messages is critical if each message is 5 MB, but trivial if each message is 100 bytes.
You must alert on lag time, not just message count. You need specific alert thresholds to catch silent failures. Consumer lag is the most critical metric in Event-Driven Architecture for Microservices.
Configure these alerts:
- Consumer lag exceeds 1,000 messages for more than 5 minutes.
- DLQ depth is greater than 0.
- Message processing error rate exceeds 5% over a 5-minute window. 4. Schema registry rejects exceed 0. These alerts catch issues before they impact the business.
If your DLQ fills up, you have a bug or a schema mismatch that needs immediate attention.
Ready to build something that lasts?
Response within 24 hours. No commitment required.
Frequently Asked Questions